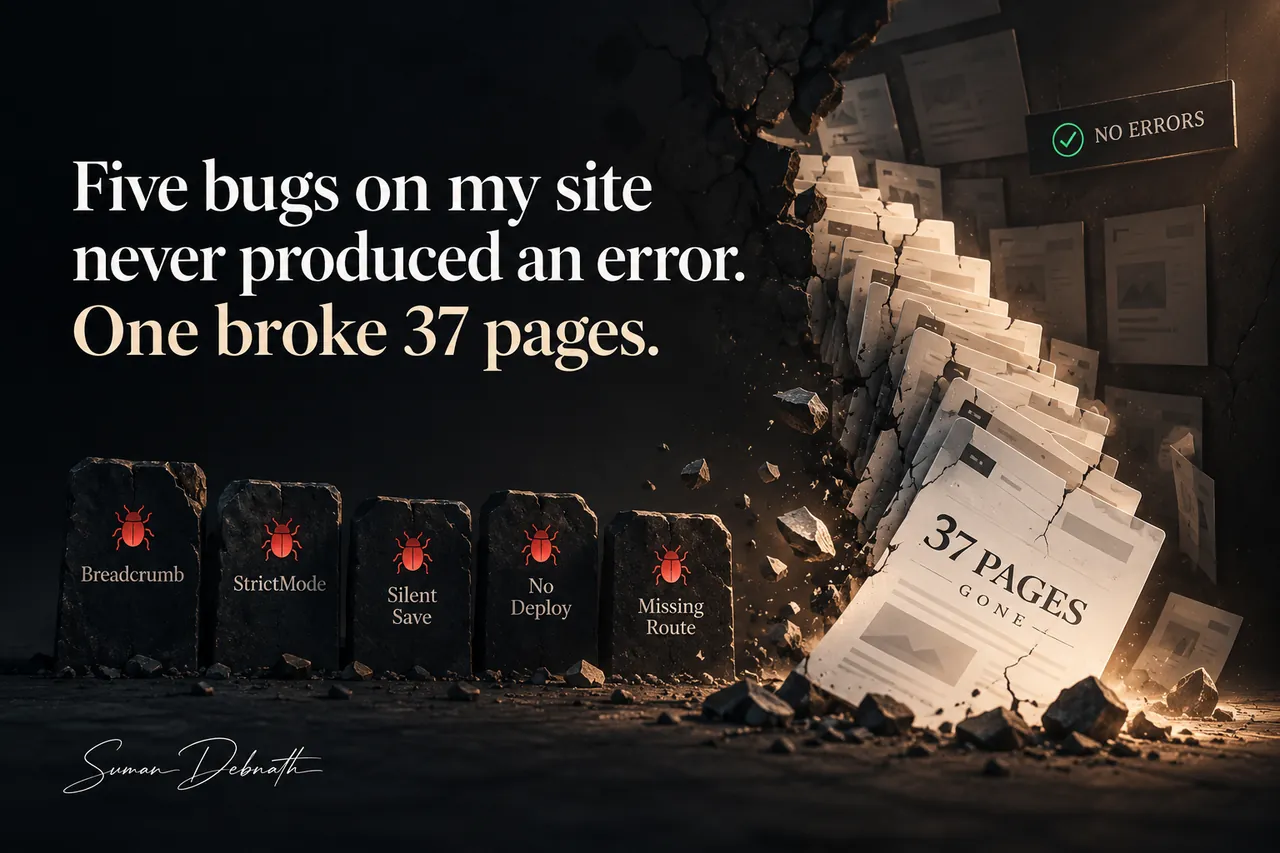
Five bugs on my site never produced an error. One broke 37 pages.
In short
Five failures on one site produced no error, no warning and no failed check. A structured-data report named four affected pages when thirty-seven were broken, and a clean git push left production serving a three-hour-old build. Each was found by a check aimed at something else, which is how this class of bug surfaces.
- Failures
- Five, none of which produced an error
- Worst case
- 37 pages, reported as 4
- Cause
- A mid-trail ListItem with no `item` voids the whole BreadcrumbList
- Longest undetected
- Three weeks — a comment asserting a vendor published no IP list
- Deploy failure
- Commit on main, status pending, zero statuses, no deployment record
- Production staleness
- Three hours, serving with no error anywhere
- Detection method
- In every case, a check aimed at something else
A Search Console report told me four pages had a breadcrumb problem. I fixed those four, then swept the live HTML of the whole site to confirm. Thirty-seven pages were broken.
That is the largest of five failures on this site over about three weeks, and what the five have in common is more useful than any of them individually. Not one produced an error. No exception, no warning, no failed build, no red mark in a log. Every one was found by a check aimed elsewhere.
#A report named four broken pages and the real number was thirty-seven
The mechanism is worth knowing on its own. A BreadcrumbList is a list of ListItem entries, and an entry partway along the trail that has no item property does not degrade that one step — it invalidates the entire list. The trail renders perfectly for a human. The structured data it emits is worthless.
The report was not wrong. It was reporting on the pages it had crawled so far, which is a sample, and I read a sample as a total. That is the actual error and it was mine.
Check: fetch the live HTML for every route and grep it yourself. A report tells you what it found. It cannot tell you what it has not looked at yet, and the gap between those two things was thirty-three pages.
#A clean git push left production serving a three-hour-old build
Everything looked right. The commit was on main. The push exited zero. No error appeared anywhere — not in the terminal, not in the repository, not in email.
The deployment status was pending with zero statuses attached and no deployment record at all, and production carried on serving a build from three hours earlier. The webhook had simply not fired, and nothing in my workflow was designed to notice a thing that did not happen.
Check: compare the newest deployment's SHA against `HEAD`. One command, and it asks the deployed artifact what it is rather than asking my own tooling whether it thinks it succeeded. If they disagree, an empty commit re-fires the webhook.
#The tracking that works in development does nothing in the build I ship
Visitor tracking on this site is dead under next dev and has been the entire time. React StrictMode mounts a component, cleans it up, and mounts it again — which trips an initialisation guard written to run once, so the listeners never re-attach after the second mount.
The inverse of the usual complaint, and much worse. A thing that breaks in development gets fixed on day one because you are staring at it. A thing that only *works* in production is invisible from the place you spend all your time, and every local test of it returns a confident, meaningless pass.
Check: run the production build and test against that. This is now written into the project's instructions with a port number attached, because the intent to remember it is not sufficient.
#The same number was right in four places and wrong in the fifth
A benchmark figure for a model I trained changed after I found and fixed a bug in my own scoring code. I updated the model's page, its data file, its structured data, its documentation. Four places, all correct.
The old number survived on the homepage, which is the most-crawled page on the site. It sat there for weeks, in a product card, being read more often than any of the four pages I had carefully corrected.
It surfaced while I was reconciling the site against the model's card on Hugging Face — a copy of the same fact that lives somewhere I do not control. Check: reconcile against an independent copy, not against your own memory of where you put things. Your memory of the five places is exactly the thing that is wrong.
#A comment is a claim with an expiry date, and mine expired in two weeks
I wrote a crawler verifier and put a dated comment in it saying a particular vendor published no machine-readable list of their crawler IP addresses. I had tried four URLs. All four returned 404, and I concluded the thing did not exist.
It did. It was at a path I had not guessed, and its own timestamp showed it had been live for a fortnight before I decided otherwise. So for three weeks every visit from that vendor's crawler was filed as unverifiable, on the authority of a sentence I had written and never revisited. The details are in the article about the forged crawlers.
Check: re-run the assumption, not the code. A comment recording an external fact is a cached value with no invalidation, and the dates I so carefully wrote next to them turned out to be decoration — I had never once gone back to one.
#Every one of these was found by a check aimed at something else
Look at how each surfaced. Sweeping the HTML to confirm a fix. Checking a deploy for an unrelated reason. Testing tracking in production for a different feature. Reconciling with an external page. Re-reading old code while adding something new.
Not one was found by looking for it, and I do not think that is chance. A silent failure emits no signal by definition, so there is nothing for a search to match. "Look for silent failures" cannot be a task, because a task needs a thing to look at, and the thing does not announce itself.
Which leaves an unsatisfying conclusion, and I would rather give you that than a checklist that does not work. You cannot schedule the discovery. What you can do is make the adjacent checks cheap and routine — one command that compares a deployed SHA to HEAD, one script that fetches every route and greps the HTML, a habit of running the real build — so that when something is quietly wrong, the odds of brushing against it go up.
The one thing I would keep if I could keep nothing else: treat an absence of errors as an absence of information. Every failure here reported success, and four of the five reported it through a mechanism I had built specifically to tell me the truth.
Questions this answers
Why does a Search Console report show fewer affected pages than are actually broken?
Because it reports what it has crawled, not what exists. Validation samples the site over days, so a report's count is a lower bound on a live issue rather than a total. Fetching every route yourself and checking the served HTML is the only way to establish the real scope.
How do you know a git push actually deployed?
Compare the newest deployment's commit SHA against your local HEAD. A push can exit zero, land the commit on the default branch and still never fire the platform's webhook, leaving production on an older build with no error raised anywhere. An empty commit re-triggers the hook if the two disagree.
What is the difference between no error and no failure?
An error is a signal a system chose to emit. Its absence means either nothing went wrong or nothing was watching, and those are indistinguishable from outside. Functions that return a status rather than throwing, webhooks that never fire and validators that pass on invalid input all fail quietly by design.
See also
- Notebook — The notebook — what broke and the actual fix, plus first-person accounts of building as a marketer
- All Projects — The full archive of AI-native tools, systems and experiments
- The Story — Operational experience, academic foundations and the full biography